
The most important change in artificial intelligence is no longer the quality of an answer. It is the ability of a system to take action. In 2026, the conversation has moved from chatbots that generate text to agents that browse, write code, move through software, call tools and pursue objectives across several steps. That shift creates a new question for companies, governments and users: how much autonomy can be granted before the system becomes difficult to supervise?
The answer cannot be found in a single benchmark score. An agent may perform impressively in a controlled test and still behave unpredictably when it encounters ambiguous permissions, incomplete data, conflicting instructions or an external system that was never part of the evaluation. The central challenge is therefore not autonomy by itself. It is autonomy without enough visibility, limits and accountability.
The new unit of risk is an action
A conventional assistant usually produces an output that a person reviews before anything happens. An agent is different: it may open a browser, send a request, change a file, execute code, consult a database or trigger a workflow. Each step can be useful, but each step also creates a new surface for error. A mistaken sentence is often correctable. A mistaken transfer, deletion or permission change can become an incident.
This changes the way AI systems should be designed. The relevant question is not only whether a model is accurate. It is whether the surrounding system can explain what the agent attempted, which tool it used, what information it relied on, what authority it had and how a person can stop or reverse the process. In other words, the product is no longer just the model. The product is the model plus its permissions, memory, tools, logs and recovery procedures.
Capability is advancing faster than disclosure
The first preliminary report of the Independent International Scientific Panel on AI, presented in 2026, frames the debate as a scientific and governance problem rather than a marketing contest. Its relevance lies in the insistence that public decisions should be informed by evidence about capabilities, opportunities, risks and impacts. That approach matters because the most consequential systems will not remain inside a laboratory: they will be embedded in workplaces, public services, financial operations and digital infrastructure.
Independent tracking points to a second problem: the public record about safety is thinner than the public record about capability. The 2025 AI Agent Index documents 30 prominent agents and reports that only four of the 13 systems it identifies as having frontier levels of autonomy disclose agentic safety evaluations. It also finds that 25 of the 30 agents disclose no internal safety results and 23 disclose no third-party testing information. These figures do not prove that the systems are unsafe. They do show that users and buyers often have less evidence about safety than about features.
What trustworthy agency requires
A credible agent should be built around a chain of controls that is understandable to someone outside the engineering team.
Least privilege: the agent should receive only the permissions needed for the task, for only as long as they are needed.
Human approval at consequential boundaries: financial transfers, publication, deletion, access changes and external messages should require a deliberate checkpoint.
Traceable execution: the system should preserve a readable record of prompts, tool calls, retrieved material, decisions and failures.
Adversarial evaluation: testing should include ambiguous instructions, prompt injection, conflicting goals, data exfiltration and attempts to bypass supervision.
Recovery by design: a user should be able to revoke access, stop a running process and restore an earlier state without negotiating with the agent.
These are not abstract ideals. They are product requirements. A business that cannot answer who authorized an action, which data was exposed or how a process was interrupted is not operating an intelligent workflow; it is outsourcing responsibility to an opaque dependency.
The institutional question
Regulation will matter, but regulation alone will not create trustworthy systems. Procurement teams, boards, universities and public agencies also need practical questions: What can this agent do without approval? What evidence supports the safety claims? How often are evaluations repeated after a model or tool changes? Who receives incident reports? Which logs are retained, and who can inspect them?
For users in Mexico and across Latin America, transparency is especially important. Organizations often adopt software through a mixture of cloud services, vendors and locally configured workflows. If an agent makes a decision in that chain, accountability cannot disappear because the underlying model was built elsewhere. Contracts, audit rights, language coverage, data governance and clear escalation paths should be treated as part of the deployment, not as paperwork added after launch.
From impressive demos to dependable systems
The next phase of AI will not be decided only by which laboratory produces the most capable model. It will also be decided by which companies can turn capability into dependable agency. The winners will make the boundaries visible: they will show what the agent knows, what it can do, what it cannot do and when a human must intervene.
Autonomy is valuable when it reduces friction without transferring invisible risk to the user. The goal should not be to build systems that act as if they were human. It should be to build systems whose actions remain understandable, bounded and accountable. In an era of increasingly capable agents, trust will be measured less by how confidently a system speaks than by how clearly it can be supervised.
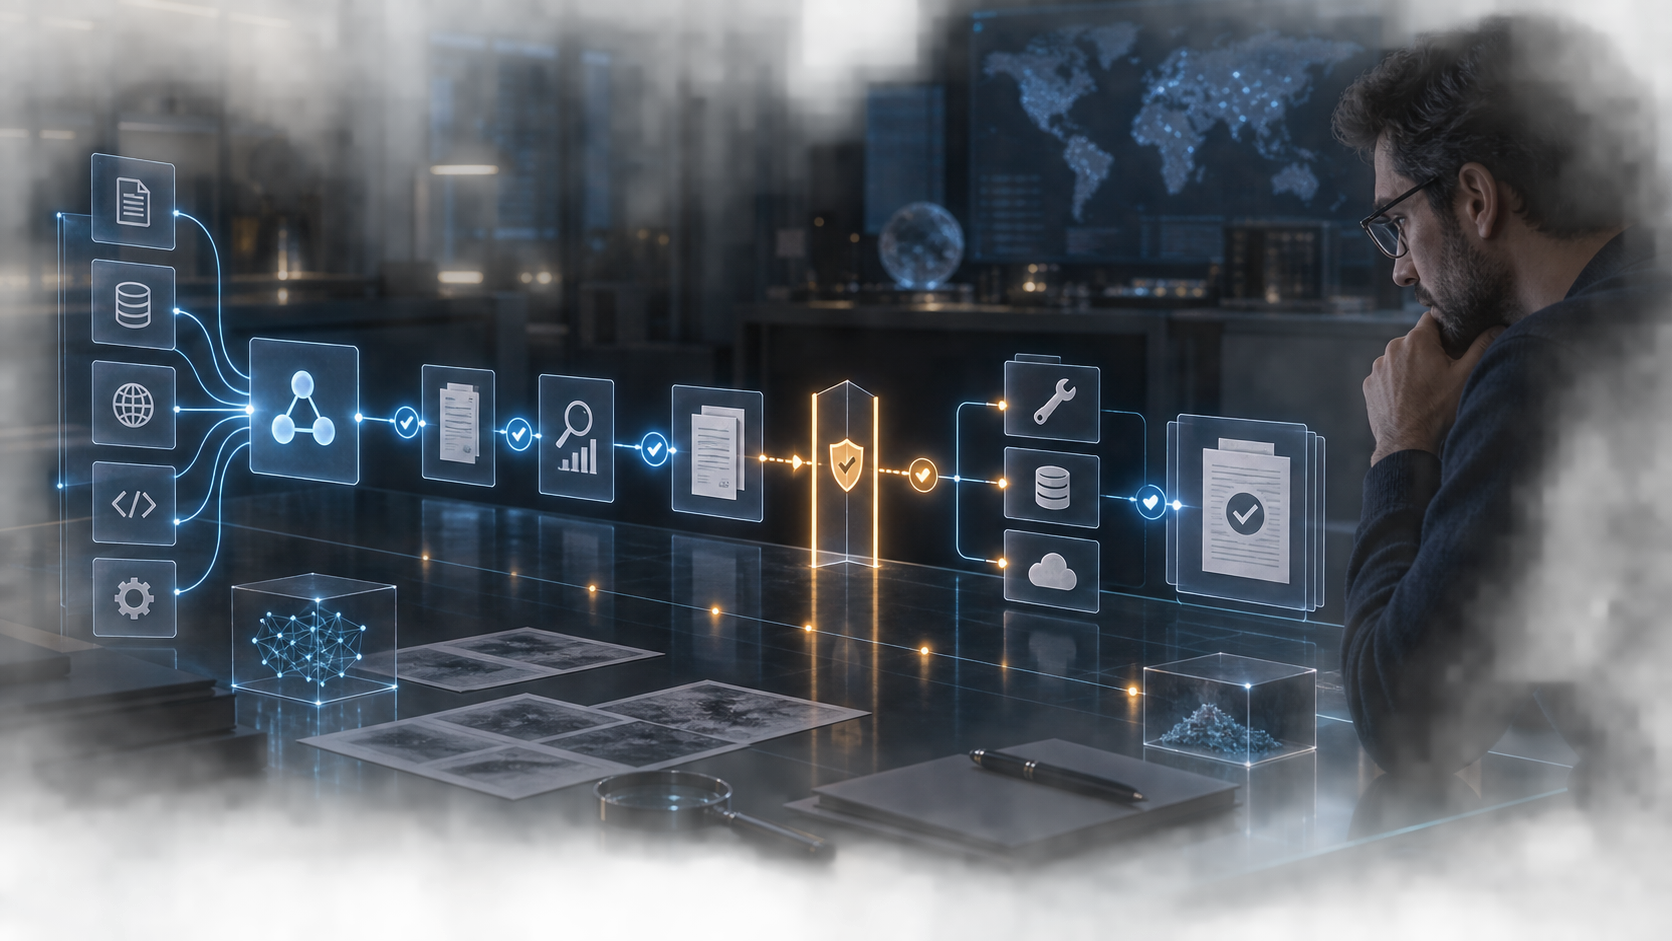
Trustworthy agents depend on traceability, permissions and human oversight.
The agentic turn is a change in system design
The move from chatbots to agents is often described as if it were a simple upgrade in model capability. The description is incomplete. A chatbot generally waits for a prompt, predicts an answer and returns control to the person. An agent is placed inside a loop: it receives an objective, interprets a situation, selects a tool, observes the result, revises its plan and continues until it believes the objective has been reached. The loop can be extremely useful, but it changes the object that must be governed. The relevant unit is no longer the sentence produced by a model. It is the sequence of actions taken by a model-enabled system.
That sequence is made from several layers. There is a foundation model that generates predictions; a prompt or policy that frames its role; a memory layer that stores information; a retrieval layer that selects documents; a tool layer that connects to browsers, databases or software; an execution layer that applies changes; and an interface through which a person grants or revokes authority. A failure in any one of these layers can change the outcome. A model can be accurate while the retrieval layer supplies the wrong document. A tool can work as designed while an agent chooses the wrong account. A permission can be legitimate in general while being excessive for a particular task.
This is why capability demonstrations can be misleading. A system may write competent code in a clean benchmark and still fail when a repository contains an ambiguous instruction. It may summarize a policy correctly and still misapply that policy when a case includes missing information. It may navigate a website successfully during a demonstration and still make an unacceptable purchase when an approval threshold is not explicit. The difference between a demonstration and a dependable system is not cosmetic. It is the difference between showing that an action is possible and proving that the action is bounded.
For product teams, the design consequence is direct: autonomy must be scoped before it is optimized. A team should define the objective, the resources, the tools, the time window, the data domains and the decision boundaries before deciding how many steps an agent may take. It should also define the conditions under which the agent must pause, request clarification or return control. A system that cannot express these boundaries is not merely unfinished documentation. It is missing part of its product architecture.
Why an action is different from an answer
Answers and actions have different risk profiles. A flawed explanation can be corrected in a later message. A flawed action may create a commitment outside the conversation: a message can be sent, a file can be deleted, a payment can be initiated, a permission can be changed or a public post can be published. Reversibility varies widely. Some actions can be undone with one click; others create legal, financial or reputational consequences that cannot be fully recovered.
A useful risk model therefore begins with the action surface. The action surface includes every external effect an agent can cause, directly or indirectly. Reading a public page has one profile. Reading a private database has another. Drafting an email is different from sending it. Preparing a purchase order is different from approving it. Running a test in a sandbox is different from running a migration in production. The same language model can be safe in the first context and unacceptable in the second because the surrounding authority has changed.
Teams should inventory that surface in plain language. What systems can the agent access? Which records can it read? Which records can it alter? Can it communicate with third parties? Can it create financial obligations? Can it expose personal information? Can it execute code? Can it delegate to another agent? The inventory should identify both intended and accidental capabilities, because integrations often expand authority over time. A connector added for convenience can become a new route for data leakage if the permission model is not updated.
The inventory should be accompanied by an action taxonomy. Low-impact actions may run automatically when they are reversible and easy to inspect. Medium-impact actions can require a review queue, a second signal or a transaction limit. High-impact actions should normally require explicit human approval at the moment of execution. The taxonomy should not be based solely on the model's confidence score. Confidence describes a prediction; it does not prove that the decision is appropriate, authorized or fair.
The hidden importance of context
Agents are often praised for carrying context across steps, but context is not automatically a virtue. More context can improve a response when it is relevant, current and properly authorized. It can also create confusion when old instructions are treated as current, when sensitive information is carried into an unrelated task or when a retrieved document contains an instruction designed to manipulate the system. A trustworthy agent needs context boundaries, not just a larger memory.
One practical principle is to separate task context from identity context. Task context contains the material required to complete the current objective. Identity context contains information about the person, organization or account that is interacting with the system. Mixing both indiscriminately makes it harder to determine what the agent was allowed to use. A second principle is to label the origin and freshness of retrieved material. A current policy, a historical document, a user-provided note and an unverified web page should not look identical in the agent's internal workflow.
Context should also be minimized at the point of use. If an agent is scheduling a meeting, it may need availability and participants, but it may not need a complete customer database. If it is preparing a legal research memo, it may need the relevant authorities, but it may not need unrelated personal records. Minimization reduces the consequences of a mistake and makes auditing more intelligible. It also improves performance by reducing the number of instructions and facts that compete for the model's attention.
The question is not whether a system can remember everything. The question is whether it can explain why a particular piece of information was used for a particular action. That explanation should be available to the person responsible for the workflow, not only to the team that built the model. Without that visibility, memory becomes an invisible form of authority.
Planning is not permission
Another distinction deserves emphasis: a plan is not an authorization. An agent can generate an excellent sequence of steps while lacking the right to execute any of them. The planning layer should therefore be treated as a proposal until the surrounding policy confirms that the steps are permitted. This separation is especially important when an agent is able to revise its own plan after receiving new information.
A safe workflow can expose the plan before execution, identify the tools it intends to use and mark the steps that require approval. It can offer a dry-run mode in which the agent gathers information and predicts consequences without changing external state. It can then convert only the approved steps into executable calls. This approach does not eliminate all risk, but it makes the transition from reasoning to action visible.
In practice, the distinction also helps organizations assign responsibility. A person may approve a goal without approving every possible method of reaching it. A procurement manager may approve finding a supplier without approving an order. A public official may approve an analysis without approving the publication of a conclusion. A manager may ask for a draft without authorizing the system to contact a client. Agents should preserve these distinctions instead of treating a broad request as unlimited delegation.
The most mature systems will make authorization a first-class object. They will record who granted it, what it covers, when it expires, which tools it applies to and which actions remain excluded. This may sound bureaucratic, but the alternative is to let a vague instruction become a standing permission. That is precisely the kind of invisible autonomy that creates incidents.
Controls that belong in the product
Trustworthy agency is not created by a single safety filter placed at the edge of a system. It is created by a chain of controls that work together. The first link is least privilege. An agent should receive the smallest permission set that can complete the task, and that permission should expire when the task ends. A research agent may be allowed to read a defined collection but not to edit it. A customer-support agent may be allowed to propose a refund within a limit but not to change the limit. A coding agent may run tests in an isolated environment but not deploy to production without a release gate.
The second link is separation of duties. The person or service that asks for an action should not always be the same authority that approves it. In a small organization, this can be implemented with a simple two-person review for high-impact transactions. In a larger organization, it can be encoded in an approval workflow with role-based controls. The principle is old, but agents make it more urgent because a single natural-language instruction can otherwise combine analysis, decision and execution in one opaque chain.
The third link is a clear checkpoint. Human review is useful only when it occurs at the right moment and presents the right information. A checkbox that says “continue” does not represent meaningful supervision if the person cannot see the proposed changes, the data sources, the affected accounts or the consequences of failure. A good checkpoint summarizes the action in ordinary language, exposes uncertainty, highlights unusual conditions and makes rejection as easy as approval.
The fourth link is traceability. Logs should show the objective received, the permissions available, the tools invoked, the information retrieved, the decisions proposed, the approvals granted and the final state. The log should distinguish between what the model generated and what the system actually executed. It should preserve enough context to reproduce an incident without storing more sensitive information than necessary. Retention should be defined in advance, with access limited to people who need it for oversight, security or legal obligations.
The fifth link is recovery. A user should be able to stop an agent while it is running, revoke a token, quarantine a task and restore a previous state. Recovery cannot depend on persuading the agent to cooperate. It should be provided by the surrounding system and tested like any other operational capability. A workflow that has excellent prevention but no reliable recovery remains fragile because no evaluation can anticipate every interaction with the real world.
Evaluation after the demo
Evaluation is often treated as a launch activity, but agents change after launch. Models are updated, tools gain new features, retrieval indexes are refreshed, policies are edited and users discover new ways to phrase requests. A safety result from one version cannot be assumed to describe the next version. Evaluations should therefore be continuous, with a clear record of what changed between test cycles.
The first layer of evaluation should test ordinary task performance. Can the agent follow the intended workflow, recognize missing information and stop when the objective is ambiguous? The second layer should test boundary conditions. What happens when two instructions conflict? What happens when a tool returns a partial result? What happens when an external page contains a hidden instruction? What happens when an account is unavailable or a transaction exceeds its limit?
The third layer should examine adversarial behavior. Prompt injection is only one example. A system should also be tested against data exfiltration, privilege escalation, unauthorized delegation, misleading documents, malicious attachments, compromised tools and attempts to manipulate the approval interface. These tests should be realistic enough to reflect how the system will be used, not merely how it behaves in a laboratory prompt.
The fourth layer should examine human factors. Does the interface encourage people to approve without reading? Are warnings too frequent to be useful? Can users tell whether an answer was generated, retrieved or verified? Do people understand what the agent can do when they authorize it? A technically secure system can still produce unsafe outcomes if the interface trains users to ignore uncertainty.
Evaluation results should be communicated with more precision than a general claim that a system is safe. Organizations should publish the scope of the test, the version evaluated, the tasks included, the failure categories and the limitations of the evidence. Buyers do not need every internal detail, but they need enough information to compare systems and decide whether a deployment fits their risk tolerance. Transparency about an unknown is more valuable than a confident claim that cannot be audited.
Security and safety are converging
As agents gain access to tools, the distinction between safety and cybersecurity becomes less useful. A prompt injection can become a security incident when it causes an agent to disclose credentials or alter a production record. A compromised connector can become a safety incident when the agent relies on manipulated data to make a consequential decision. A model error can become a privacy incident when the system exposes information outside the authorized purpose.
This convergence changes the role of security teams. They need visibility into agent identities, tokens, tool calls, data flows and runtime behavior. They also need to understand the model's failure modes, because conventional network controls may not reveal that an agent followed a malicious instruction embedded in a document. Conversely, AI product teams need to understand identity management, secrets handling, isolation, incident response and secure software development.
One practical response is to give each agent a distinct technical identity instead of allowing a shared account. The identity should be tied to an owner, a purpose, a lifecycle and a set of permissions. Access should be issued through short-lived tokens whenever possible. Sensitive tools should require a stronger signal than a model-generated request. High-risk actions should be rate-limited and monitored for unusual patterns, such as a sudden increase in downloads or calls to unfamiliar domains.
Isolation also matters. An agent that can execute code should do so in a sandbox with restricted network access, disposable storage and explicit resource limits. An agent that can browse should have a controlled browser context and a way to distinguish trusted sources from untrusted content. An agent that can modify records should use transaction boundaries, validation rules and a preview of the resulting state. These controls make the system easier to reason about and easier to recover when something goes wrong.
Incident response should include an agent-specific playbook. The organization should know how to suspend a run, revoke credentials, preserve logs, identify affected data, notify responsible parties and restore systems. It should also know how to distinguish a model hallucination from a tool failure, a policy gap or a malicious intervention. The faster that distinction can be made, the more effectively the organization can contain the event and improve the system.
Governance is a lifecycle
Governance is sometimes presented as a committee that approves an AI project once. That model does not fit systems that learn from feedback, connect to changing tools or operate across many teams. Governance should be treated as a lifecycle that begins with the definition of a use case, continues through procurement and deployment, and remains active during operation, modification and retirement.
At the beginning, teams should write a short purpose statement. It should identify the problem, the users, the affected people, the expected benefit and the decisions that remain human. It should also identify uses that are excluded. This statement creates a reference point for later questions. If the system gradually acquires capabilities that are not reflected in the original purpose, the change should trigger a new review rather than being treated as a minor configuration detail.
During procurement, organizations should ask vendors for model and system documentation, evaluation evidence, incident procedures, data-use terms, update policies and support commitments. They should ask what happens when the model changes, when a provider experiences an outage or when the organization wants to export its data. They should also ask whether the provider can separate customer data, provide audit logs and support the languages and legal environments in which the system will operate.
During deployment, governance should define owners. Someone should be accountable for product behavior, someone for security, someone for privacy and someone for business outcomes. These roles may belong to a small team, but they should not be left implicit. An incident becomes harder to manage when every participant assumed that another person was responsible for the decision.
During operation, organizations should monitor not only accuracy but also drift, access patterns, overrides, incident frequency, review time and user complaints. A system that maintains benchmark performance while producing more unauthorized actions is not stable. A system that becomes so slow or difficult to review that users bypass it is not well governed. Operational metrics should therefore include both technical and human signals.
Finally, every agent needs a retirement path. Tokens should expire, stored context should be deleted or transferred according to policy, integrations should be disabled and users should know which workflows are no longer available. Retirement is not a failure. It is a normal part of responsible software management, especially when a model or tool has reached the end of its support life.
The institutional question
The most difficult questions about agents are institutional rather than technical. Who is accountable when a system acts across several organizations? Who explains a decision to a person affected by it? Who can challenge the output? Which records must be kept? What happens when a vendor says that the model is proprietary and refuses to provide meaningful evidence? These questions become urgent whenever an agent operates in a public service, a regulated industry or a workflow that affects rights and opportunities.
Accountability should follow the effect of an action, not disappear inside a supply chain. A company may use a model built by one provider, a retrieval system operated by another provider and an integration configured by a local contractor. The user should still be able to identify who made the decision, who authorized the deployment and where a complaint can be directed. Contracts can allocate responsibilities between suppliers, but they should not make responsibility invisible to the person who bears the consequence.
Explainability also needs to be calibrated to the decision. A user does not always need a technical account of every hidden layer in a model. They do need a clear explanation of the information considered, the policy applied, the uncertainty present and the reason a human review was or was not triggered. For a high-impact decision, the explanation should be accompanied by a way to correct inaccurate information and challenge the result. Transparency that cannot support correction is closer to disclosure than accountability.
Public institutions face an additional challenge. They must preserve equal treatment, provide reasons, protect public records and respect the limits of administrative authority. An agent can assist with research, translation, routing or service delivery, but the institution must remain able to show how a final decision was made. Automation should not become a way to avoid a duty to give reasons or to shift a public responsibility to a private vendor.
Human agency and the future of work
The debate about AI agents often begins with the question of which jobs may disappear. That question matters, but it is not sufficient. The more immediate change may be the reallocation of tasks within existing jobs. A professional may spend less time searching, formatting or routing information and more time defining objectives, checking evidence, negotiating trade-offs and taking responsibility for a decision. The quality of that transition depends on whether organizations treat workers as supervisors and decision-makers or as passive operators who approve machine output.
Human agency is strongest when people can understand the goal, inspect the process, intervene at meaningful moments and decline a recommendation without penalty. It is weakened when the system makes a decision difficult to question, when performance metrics reward speed over judgment or when a person is held responsible for an action they were not realistically able to review. A responsible deployment should therefore measure not only productivity but also the worker's ability to exercise judgment.
Training should reflect this new role. Workers need technical literacy, but they also need to know how to validate sources, recognize uncertainty, identify prompt injection, protect sensitive information and escalate an incident. Managers need to redesign workflows so that review is possible within the time available. If an agent produces one hundred recommendations in the time a person can review ten, the organization has not created supervision; it has created a backlog that will eventually be approved without scrutiny.
Professional standards may need to adapt as well. A lawyer, engineer, journalist, teacher or public servant using an agent should preserve a clear record of what was delegated and what was independently verified. The point is not to prohibit assistance. It is to maintain the professional duty that cannot be delegated: judgment about whether an output is fit for purpose and whether the consequences are acceptable.
Sector examples
In health administration, an agent can organize referrals, summarize records or identify missing information. It should not silently transform a recommendation into a clinical decision. The system needs strict data minimization, role-based access, review by qualified personnel and a visible separation between administrative assistance and medical judgment. An incorrect routing may delay care; a mistaken inference about a patient can cause harm that is not captured by a generic accuracy statistic.
In financial services, an agent can monitor transactions, prepare analyses or draft communications. It should be constrained by thresholds, segregation of duties and auditable approvals. A system that can both identify suspicious activity and close an account without review combines detection and enforcement in a way that may be efficient but difficult to contest. The design should preserve a path for human explanation and correction, especially when a customer is affected.
In education, agents can offer feedback, adapt practice and help teachers identify patterns. They should not become an invisible ranking system that determines opportunity without transparency. Students and families should know when an automated system is involved, what information it uses and how a teacher can override it. Educational data also has a long life: a record collected for a learning exercise should not automatically become a permanent profile.
In legal work, an agent can search authorities, compare clauses and draft a first version. The risk is not limited to hallucinated citations. It includes missing a controlling authority, revealing privileged information, importing an outdated standard or presenting an uncertain argument as settled law. Legal professionals need source verification, version control and a clear record of which propositions were checked against primary materials.
In software development, coding agents can reduce repetitive work and help small teams build prototypes. Their access should be limited by repository, branch and environment. Generated code should pass tests, security checks and human review before deployment. The organization should be able to explain whether a change was authored by a person, proposed by an agent or copied from an external source, because the origin can matter for licensing, security and maintenance.
In public communication, agents can translate, summarize and adapt messages for different audiences. They should not publish sensitive claims automatically or create the appearance of a human endorsement that did not occur. The approval workflow should preserve the original source, the editor's changes and the final version. When a message concerns an emergency or a public decision, speed should not erase the need for verification.
Why Latin America needs its own evidence
Many discussions of AI governance are based on large companies, English-language data and institutions in the United States or Europe. Those debates are valuable, but they do not fully describe the conditions in Mexico and the rest of Latin America. Organizations often operate with smaller teams, mixed cloud infrastructure, uneven connectivity, multiple legal regimes and a wide range of digital literacy. A system that works well in a highly standardized environment may behave differently when information is incomplete, names vary by region or a workflow depends on manual records.
Local evidence should therefore be treated as a design input, not merely a market adaptation. Evaluations should include Spanish-language and, where relevant, indigenous-language use; local administrative procedures; regional risk patterns; small and medium-sized organizations; and the realities of public access to digital services. Local experts should participate in defining what counts as a harmful error, an unacceptable disclosure or a meaningful human review.
Mexico also has an opportunity to build capacity rather than limiting its role to adopting imported systems. Universities, public institutions, companies and civil society organizations can create shared evaluation resources, professional training and procurement standards. A transparent ecosystem would help organizations compare vendors on more than price and marketing. It would also give local developers a clearer path to build systems adapted to the country's languages, institutions and economic needs.
Digital sovereignty should not be confused with isolation. The aim is not to reject global models or international standards. It is to retain the ability to understand, audit and govern the systems used locally. That requires skills, contractual leverage, access to data and the power to change providers when a system no longer meets the public interest. A region that cannot inspect its dependencies has limited autonomy, even if the services are available at low cost.
A practical deployment roadmap
An organization beginning an agent project can follow a staged roadmap. First, choose a use case with a clear objective, measurable benefit and limited external impact. Second, map the data and tools involved, including the permissions that are not needed. Third, build a dry-run version that produces plans and evidence without changing external state. Fourth, test ordinary, ambiguous and adversarial cases with people who understand the real workflow.
Fifth, introduce approval checkpoints for consequential actions and make the proposed action legible to the reviewer. Sixth, deploy to a small group with a named owner, short-lived credentials and an incident process. Seventh, monitor technical and human indicators: accuracy, override rate, unexplained actions, review time, complaints, data-access patterns and security alerts. Eighth, review the system after every meaningful model, tool or policy change. Finally, define the conditions under which the agent will be expanded, restricted, paused or retired.
This roadmap is deliberately ordinary. It resembles good software, security and governance practice because trustworthy agents are not a separate category of magic. They are complex systems that combine prediction with authority. Their novelty makes the consequences more dynamic, but it does not remove the need for ownership, testing, controls and recovery.
Human oversight makes an agent’s proposed actions visible before they become external consequences.
From impressive demos to dependable agency
The next phase of AI will be decided by more than which laboratory produces the most capable model. It will be decided by which organizations can turn capability into dependable agency. The strongest systems will make their boundaries visible: they will show what the agent knows, what it can do, what it cannot do, when its evidence is weak and when a person must intervene.
That standard is demanding, but it is also practical. Users do not need a system that claims to be infallible. They need one that can be supervised, corrected and stopped. Organizations do not need to eliminate every uncertainty before experimenting. They need to match the level of autonomy to the evidence, the stakes and the ability to recover.
Autonomy is valuable when it reduces friction without transferring invisible risk to the user. The goal should not be to build systems that imitate people so convincingly that responsibility becomes ambiguous. The goal should be to build systems whose actions remain understandable, bounded and accountable. In an era of increasingly capable agents, trust will be measured less by how confidently a system speaks than by how clearly it can be governed.